Guide
Which Database Should Your AI Agent Use?
Short answer: Postgres for state, pgvector or a vector store for recall, Redis for cache, and an analytics database for telemetry. Most agent stacks need two of those, not four, and the engine choice matters less than the amount written about it suggests.
This page answers that question first. Then it covers the workload the engine choice leaves out: the business facts your agents produce, which people and later agent runs need to read, trust, and undo.
Last verified 13 November 2026
What agents actually store
“A database for an AI agent” bundles five workloads that arrive at the same time. Separate them and the choices become obvious:
| What is being stored | Access pattern | Reasonable default |
|---|---|---|
| Application and session state | Small reads and writes, transactional, must be exact | Postgres |
| Semantic recall over documents | Approximate nearest-neighbour search over embeddings | pgvector; a dedicated vector store at large scale |
| Hot context and rate limits | Sub-millisecond, ephemeral, high churn | Redis |
| Prompt/response logs and token accounting | High-volume append, aggregate reads | ClickHouse, DuckDB/MotherDuck, or Postgres until it hurts |
| Business facts the agent produced | Read by people and later agent runs as truth; must show who changed what | A workspace with change history — such as Busabase (see below) |
Start with Postgres, and mean it
For most agent projects, Postgres alone is the right first answer, and adding a second system on day one is premature. It handles state, relations, JSON, full-text search, and — through pgvector — embeddings, well past the scale most agent products reach.
Do not reach for a dedicated vector database too early. pgvector supports HNSW and IVFFlat indexes. A separate vector service buys recall performance you probably cannot measure yet, at the cost of a second consistency domain and a second thing to operate.
Do not log prompts and responses into the same Postgres as your state. Full prompt/response capture is append-heavy and grows without bound; next to your transactional tables it becomes a vacuuming and partitioning problem within months. Give telemetry its own home early.
When a dedicated vector store or Redis earns its place
- A vector store: tens of millions of vectors with latency targets you actually measure; heavy metadata filtering combined with nearest-neighbour search (pgvector applies filters after the approximate index scan, and added iterative index scans in 0.8.0 to compensate); or frequent full re-embedding you want isolated from your primary database.
- Redis: session context, tool-call rate limits, deduplication windows, and queue state — per-request work Postgres could do, but not at the latency you want. Redis is not a system of record; treating it as one is how teams lose a day's work to an eviction policy.
Below those thresholds, the cost of operating a second system outweighs the difference. Measure before you migrate.
The question underneath the question
Every option above answers where do the bytes go. None of them answers what changed, who changed it, and can we undo it — and for agent work, that second question decides whether the project can be trusted.
Say an agent enriches 200 customer records and writes them to Postgres, correctly, with perfect permissions. Some are wrong — not malformed, just confidently false. Every constraint passed. The old values are gone. Nothing in the stack tells a later reader which rows the agent touched, what they said before, or which agent did it.
That is not an engine problem, so a different engine will not fix it. Constraints validate shape; row-level security validates permission. Neither keeps the before and after.
The layer engines leave out: every change is a Change Request
Busabase is that layer, ready-made. It runs on Postgres underneath, but agents do not write rows into it blindly. Every edit — a record, a Doc, a Skill file, a schema change — is a Change Request: a branch with immutable commits, a message, and a field-level diff. Merging moves the record forward; nothing is overwritten.
On a bare database, the same thing means audit tables, triggers, a staging table with a promotion step, and a review screen you build and maintain yourself.
- A message and a diff on every write. Each change says what it does and shows the field-level before and after.
- Know which agent did it. The author, and the key or tool the change came through, stay on the commit.
- Undo is built in. Records, Docs, and Skills keep their full history; merging never overwrites, and any change can be rolled back.
- Review when you choose. Writes with write access merge at once. Give an agent a proposal-only key, or send a change with
autoMerge: false, and it waits in the Inbox for a person to approve or send back. Read the Change Request docs.

Build that layer on Postgres, or use Busabase
Rows are the jobs teams have to cover for agent-written business data. The last row is Postgres's home ground, and the right answer there is Postgres.
| What you need | Busabase | Build it yourself on Postgres |
|---|---|---|
| See every change before and after, and which agent made it | Built in — field-level diff, author, and the key or tool on every commit | Audit tables and triggers you design; old values are lost unless you keep them |
| Hold one agent's changes for review | Yes — a proposal-only key sends its changes to the Inbox | A staging table, a promotion step, and a review UI |
| Roll back a single bad change | Yes — any Change Request can be reverted | Point-in-time recovery restores the whole database, or hand-written fixes |
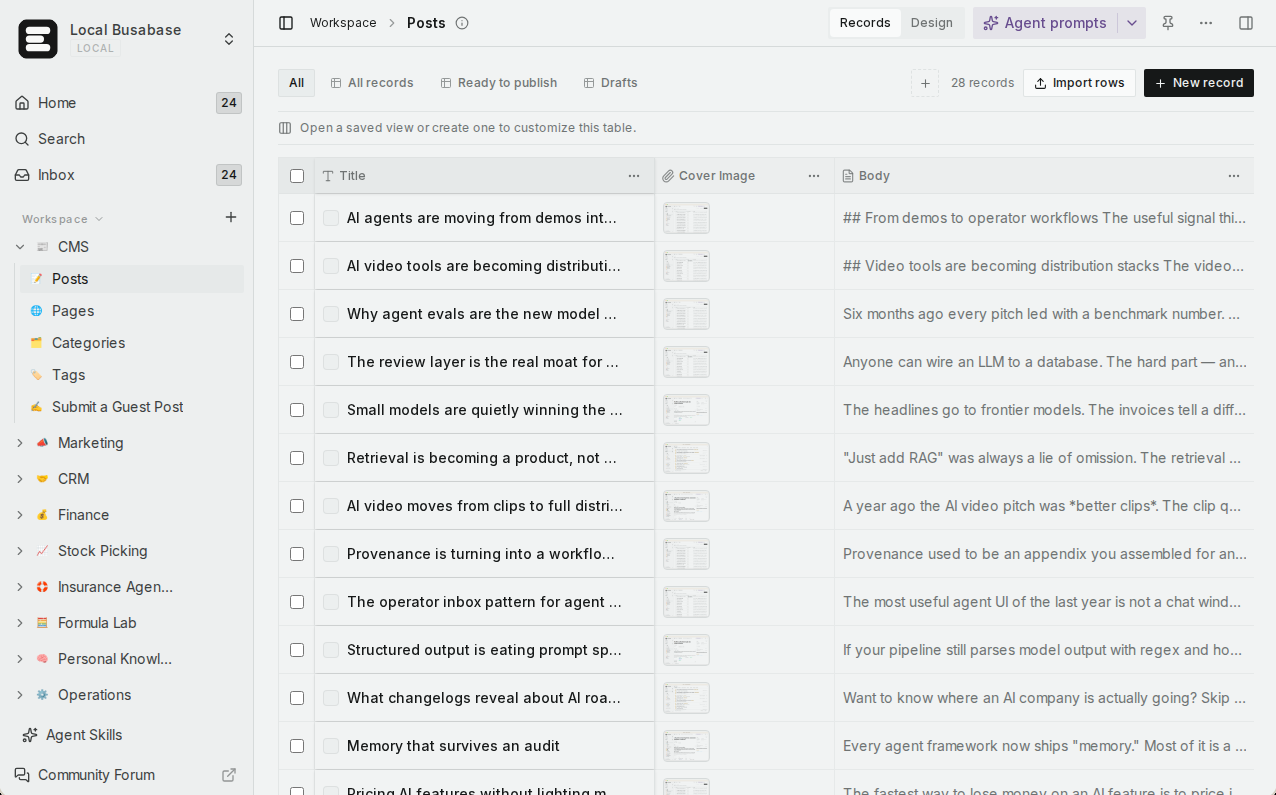
| Let teammates read and fix what agents wrote | Yes — table, gallery, kanban, calendar, and Gantt views | An admin panel or internal tool you build |
| Keep docs, files, and Skills next to the records | Yes — one tree, one permission model | Separate storage and a separate wiki |
| Search exact text across all of it | Yes — one grep across files, Doc bodies, records, and prompts | SQL and full-text search over your own tables |
| Turn the data into an app or a website | Yes — AirApps, including websites on your own domain | Bring your own front end and hosting |
| Connect Claude Code, Codex, and other agents | Yes — MCP, CLI, OpenAPI, webhooks, and plugins | Write and secure your own tools or MCP server |
| Your application's transactional state, vector recall, and high-volume writes | Not its job — use Postgres (and pgvector) | Yes — this is what Postgres is for |
What else Busabase gives your agents and your team
Visual tables people can read
A team knowledge base
grep across everything
Shared team Skills
AirApps on live data
Websites on your own domain
Agents connect in minutes
Open source, runs anywhere
Flat, predictable pricing
Coming next
These are being built now. They are not available yet, and this page will say so until they ship.
App usersIn development
OntologyIn development
Fine-grained permissionsIn development
Using them together
This is not either/or. Keep your application's state in Postgres, recall in pgvector, cache in Redis, and telemetry in an analytics store. Put the facts agents produce for your team — research, customer records, content, operating docs — in Busabase, where people can read them and every change is traceable. If you are weighing a hosted Postgres specifically, see Busabase vs Supabase.
Disclosure: Busabase itself runs on Postgres — PGlite when it runs locally, standard Postgres in Cloud. We are not neutral about the engine question, but we are boring about it.
Frequently asked questions
Is Postgres good enough for AI agents?
Do I need a vector database?
Where should I store prompts and responses?
Where should agent-written business data live?
What database does Busabase use?
Can one database do all of this?
Next step
If the engine question is settled and the “what did the agent change” question is the one you are stuck on, connect an agent to Busabase and read the first Change Request it leaves.
Related: System of record for AI agents · Compare Busabase · Busabase vs Supabase · Change Requests · What is an agent workspace
Sources: pgvector README